
The short answer
First prove what “not showing” actually means.
A missing brand search, an unindexed page, and a page that ranks poorly for a competitive service query are different problems. Check whether Google knows the URL, can fetch it, may index it, selected it as the canonical, and considers it relevant to the tested query.
Work through those questions in order. Publishing more copy cannot repair a blocked request, and requesting indexing cannot resolve a page-ownership conflict.
Step 01 / Name the symptom
Separate four problems people call “not on Google.”
The entire domain appears absent
Test the homepage and a known internal page in Search Console. Check host, protocol, server access, global directives, and whether the site is genuinely new.
One important URL is missing
Inspect that exact URL, its response, internal links, noindex state, canonical target, rendered content, and discovered duplicates.
The page exists but not for a keyword
Confirm the intended page is indexed, then compare query intent, page role, evidence, location relevance, and competitive strength.
Google shows a different page
Review canonicals, redirects, internal anchors, duplicate copy, and whether the other page is actually a better match for the query.
Indexing answers “may this page appear?” It does not answer “should this page rank for this query?”
Step 02 / Follow the pipeline
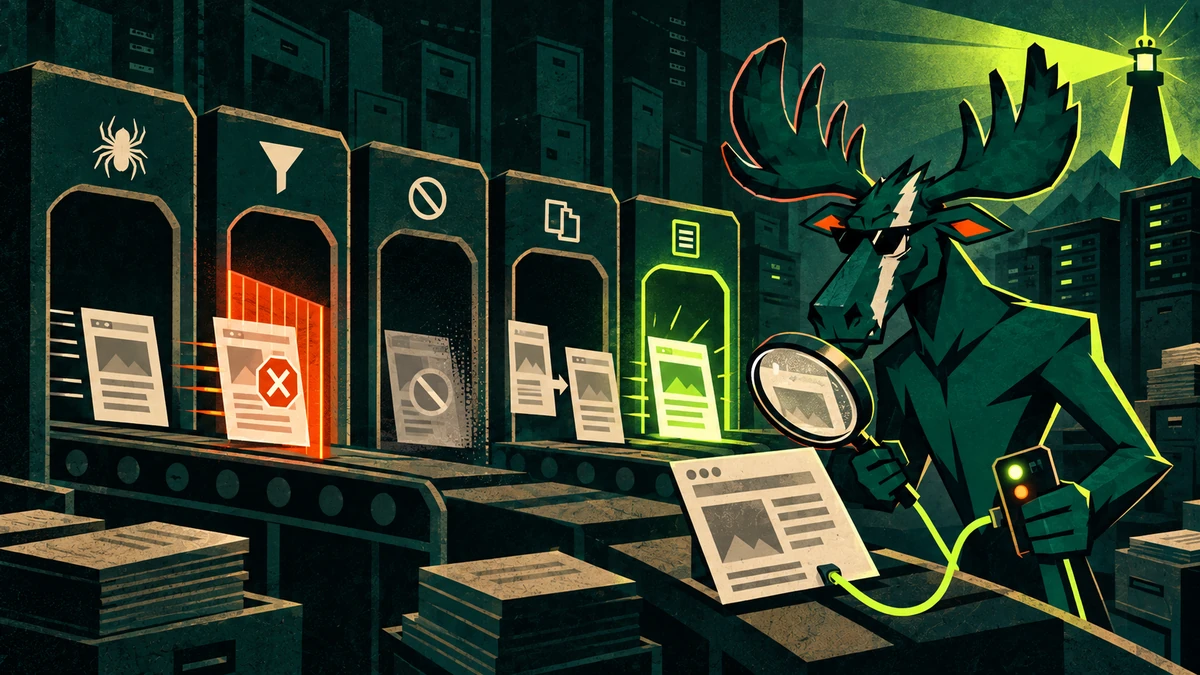
A page must survive five layers before it can compete.
- 01
Discovery
Can Google find a crawlable link or sitemap reference to the preferred URL? A page known only through a form, script event, or private route may be effectively orphaned.
- 02
Access
Does the URL return the intended content without a block, challenge, login, redirect mistake, server error, or robots restriction?
- 03
Rendering and directives
Does the processed page expose its core copy and links, and does it avoid an accidental noindex directive? Google must be able to crawl a page to see its noindex rule.
- 04
Canonical selection
Do redirects, rel=canonical, internal links, sitemap entries, and content all support the same representative URL?
- 05
Relevance and competition
Does the selected page satisfy the query and location better than the available alternatives? Eligibility is not a ranking promise.
Step 03 / Read the evidence
Translate the report into the next test—not a guess.
| Observed state | What it suggests | Next useful check |
|---|---|---|
| Blocked by robots.txt | Google is restricted from crawling the URL. | Confirm whether the block is intentional. Do not rely on robots.txt to keep a known URL out of results. |
| Excluded by noindex | Google found a noindex directive after crawling. | Remove it only if the page should be eligible, then verify the live rendered directive. |
| Alternate page with canonical | The URL points to another representative URL. | Confirm the target is truly equivalent and that internal links support it. |
| Duplicate without user-selected canonical | Google found similar URLs but no clear owner from the site. | Choose the owner and align canonical, links, redirects, and sitemap signals. |
| Crawled, currently not indexed | Google fetched the page but has not selected it for the index. | Inspect duplication, usefulness, rendered content, page role, and ownership; do not just resubmit it. |
| Discovered, currently not indexed | Google knows the URL but has not yet crawled it. | Check server health, internal importance, duplicate URL production, and whether the page is worth requesting. |
Search Console labels describe an observed processing state, not a guaranteed permanent diagnosis. Recheck the live URL and the surrounding signals before prescribing a fix.
20-minute triage
Test one important URL from request to query.
- Minutes 0–5 / ConfirmRecord the exact URL, query, location, device, observed result, and intended page owner. Inspect the URL in the correct Search Console property.
- Minutes 5–10 / FetchCheck the live response, redirect path, robots access, meta robots or header directives, rendered content, and canonical.
- Minutes 10–15 / ReconcileCompare internal links, sitemap entry, host variants, parameter versions, and pages covering the same service or place.
- Minutes 15–20 / DecideClassify the failure as discovery, access, directive, ownership, or relevance. Make one evidence-based change and define how it will be validated.
For the control-level decisions behind this triage, use the robots.txt versus noindex versus canonical guide.
Connect diagnosis to execution
The correct control is the one the evidence calls for.
MooseRank's technical SEO and site foundation work connects the diagnosis to implementation, live validation, and the pages that support qualified demand.
As an Long Island SEO company, MooseRank keeps technical decisions tied to the service, market, page owner, and customer action the campaign is meant to grow.
Protect the search path
Fix the constraint with the clearest business consequence.
Bring the page, migration, or indexing problem. MooseRank will trace the evidence, choose the right control, and define what complete looks like.
Straight answers
Common questions
01Why is my website not showing up on Google?+
The site may be undiscovered, inaccessible, excluded from indexing, consolidated under another URL, too new to have been processed, or simply not competitive for the query being tested. First determine whether the whole site, one page, or one keyword is missing.
02Does submitting a sitemap make Google index my website?+
No. A sitemap helps Google discover preferred URLs, but Google does not guarantee crawling or indexing. The pages still need to be accessible, indexable, useful, internally discoverable, and consistently canonicalized.
03How can I check whether Google indexed a page?+
Use Google Search Console's URL Inspection tool for the property and page you control. A site: search can provide a rough clue, but Google says it is not a complete list and should not replace Search Console diagnostics.
04Should I keep requesting indexing until the page appears?+
No. Repeated requests do not repair a blocked, noindexed, duplicated, inaccessible, or low-value page. Correct the underlying condition and allow time for recrawling and processing.
05Can a page be indexed but not rank for my keyword?+
Yes. Indexing only makes a page eligible to appear. Ranking for a query also depends on whether the page is a relevant result, whether Google selected it as the representative URL, and how it compares with other eligible results.
Primary sources
Google documentation reviewed
- Google Search Central: Crawling and indexing FAQ
- Google Search Central: Ask Google to recrawl your URLs
- Google Search Central: Canonicalization
- Google Search Central: Robots meta tags
Research note: official documentation was reviewed September 21, 2026. The diagnostic frameworks and examples are MooseRank's application of those documented mechanisms to service-business websites; they are not Google ranking-factor labels or guarantees.
About the author
The Moose
The Moose is the Founder of MooseRank and writes about SEO strategy, AI search visibility, and the evidence businesses should use to make better search decisions.
Meet The Moose and the MooseRank system