
The short answer
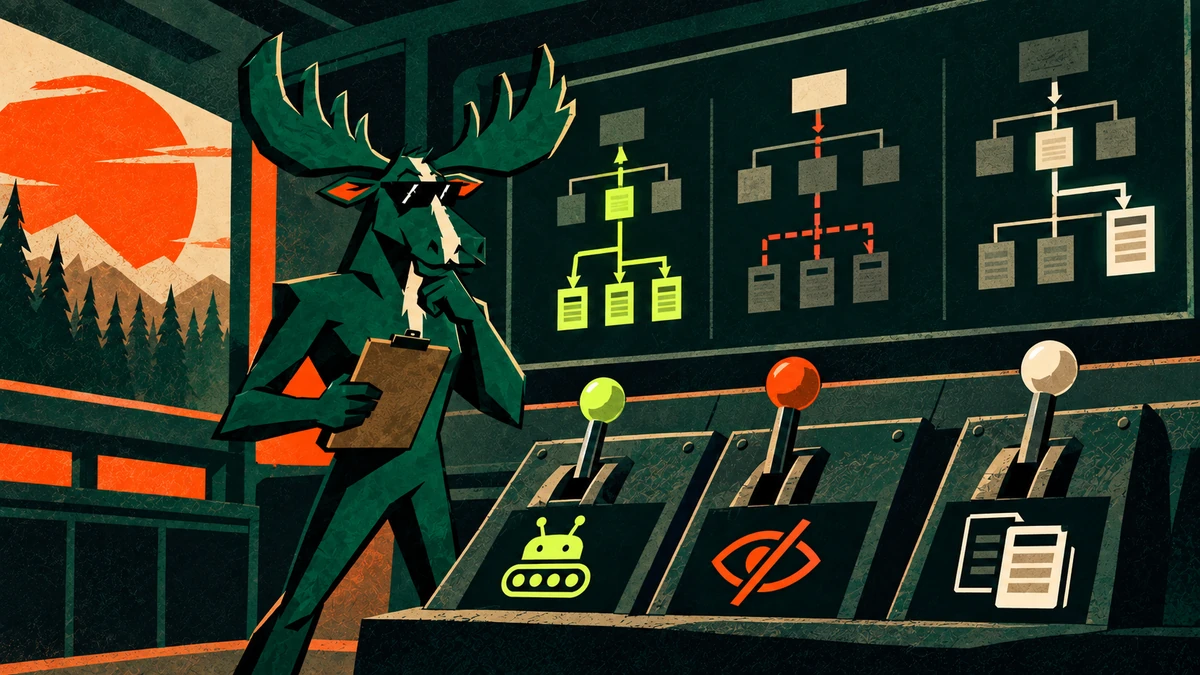
Robots controls crawling. Noindex controls eligibility. Canonical signals ownership.
Use robots.txt to manage whether compliant crawlers may request a path, noindex to exclude a crawlable page from search results, and rel="canonical" to identify the preferred representative among duplicate or very similar URLs.
Add a fourth control to the comparison: use a 301 or 308 redirect when the old URL should permanently send users and crawlers to a relevant replacement.
Outcome matrix
Match the control to the job it actually performs.
| Your goal | Use | What it does | What it does not do |
|---|---|---|---|
| Limit crawling | robots.txt | Restricts compliant crawlers from requesting matching paths. | Does not reliably remove a known URL from search results. |
| Exclude a page from Search | noindex | Makes a crawlable page ineligible for Google Search after the directive is processed. | Does not consolidate the page's duplicate signals into another URL. |
| Consolidate duplicates | rel="canonical" | Signals the preferred representative for duplicate or very similar pages. | Is not an absolute command and does not prevent crawling. |
| Move a URL permanently | 301 or 308 | Sends users and crawlers to a relevant replacement and signals a permanent move. | Does not make an irrelevant destination equivalent to the old page. |
Decision sequence
Ask four questions in this order.
- 01
Should the URL remain usable?
If no, and a relevant replacement exists, redirect it. If no equivalent exists, a genuine 404 or 410 may be more honest than sending everything to the homepage.
- 02
Should the page appear in search?
If the page must remain usable but should not be indexed—such as a private utility or thank-you page—use noindex and allow crawling.
- 03
Is it a duplicate that must remain accessible?
If several equivalent URLs must exist, choose the preferred one and align canonical, internal links, sitemap inclusion, and any redirects.
- 04
Is crawler access itself the problem?
Use robots.txt for crawl management, not as a substitute for removal, canonicalization, authentication, or a site architecture decision.
Signal conflicts
The most expensive mistakes combine incompatible instructions.
- Blocked + noindexIf crawling is blocked, Google may not see the noindex directive. Allow crawling long enough for the exclusion directive to be processed.
- Noindex + canonicalOne instruction asks for exclusion while another nominates a representative. Decide whether the URL should be excluded or consolidated instead of sending mixed intent.
- Canonical A + internal links BTemplates nominate one owner while navigation and contextual links promote another. Align the signals around the defensible owner.
- Redirect A + sitemap AThe sitemap keeps submitting a retired URL. List the final canonical destination and update internal links so the redirect is not the normal route.
A control is not correct because it suppresses a warning. It is correct when it produces the intended user and search outcome.
Service-business examples
Apply the distinction to pages a local campaign actually uses.
- homepage and primary service pages;
- useful location pages with distinct evidence;
- case studies and substantial guides;
- contact and pricing pages when publicly useful.
- redirect retired service URLs to genuine replacements;
- noindex internal search or thank-you utilities;
- canonical unavoidable tracking or print duplicates;
- block non-public crawl spaces only when access rules are appropriate.
Location architecture needs special care. The canonical guide for service and location pages explains when pages are duplicates and when separate local intent deserves separate ownership.
Connect diagnosis to execution
The correct control is the one the evidence calls for.
MooseRank's technical SEO and site foundation work connects the diagnosis to implementation, live validation, and the pages that support qualified demand.
As an SEO services company on Long Island, MooseRank keeps technical decisions tied to the service, market, page owner, and customer action the campaign is meant to grow.
Protect the search path
Fix the constraint with the clearest business consequence.
Bring the page, migration, or indexing problem. MooseRank will trace the evidence, choose the right control, and define what complete looks like.
Straight answers
Common questions
01What is the difference between robots.txt and noindex?+
Robots.txt manages crawler access to URL paths. Noindex tells a search engine not to include a page in its index after it can crawl and read that directive. If robots.txt blocks the page, Google may not see the noindex instruction.
02Does a canonical tag stop Google from indexing a page?+
Not in the same way as noindex. A canonical is a signal that another URL should represent a set of duplicate or very similar pages. Google may choose a different canonical if the site's signals conflict.
03Can I put noindex in robots.txt?+
No. Google does not support noindex rules in robots.txt. Use a robots meta tag or X-Robots-Tag on a crawlable response when the page should be excluded from Google Search.
04Should I use a canonical or a 301 redirect?+
Use a permanent redirect when users and search engines should stop using the old URL and move to the new one. Use a canonical when duplicate or very similar URLs must remain accessible but one should be the preferred representative.
05Should noindex pages be included in the XML sitemap?+
Usually no. A sitemap should list the canonical URLs you want considered for indexing. Including a noindex URL sends contradictory intent and makes auditing harder.
Primary sources
Google documentation reviewed
- Google Search Central: Introduction to robots.txt
- Google Search Central: Robots meta tags and X-Robots-Tag
- Google Search Central: Specify a canonical URL
- Google Search Central: Redirects and Google Search
Research note: official documentation was reviewed September 21, 2026. The diagnostic frameworks and examples are MooseRank's application of those documented mechanisms to service-business websites; they are not Google ranking-factor labels or guarantees.
About the author
The Moose
The Moose is the Founder of MooseRank and writes about SEO strategy, AI search visibility, and the evidence businesses should use to make better search decisions.
Meet The Moose and the MooseRank system